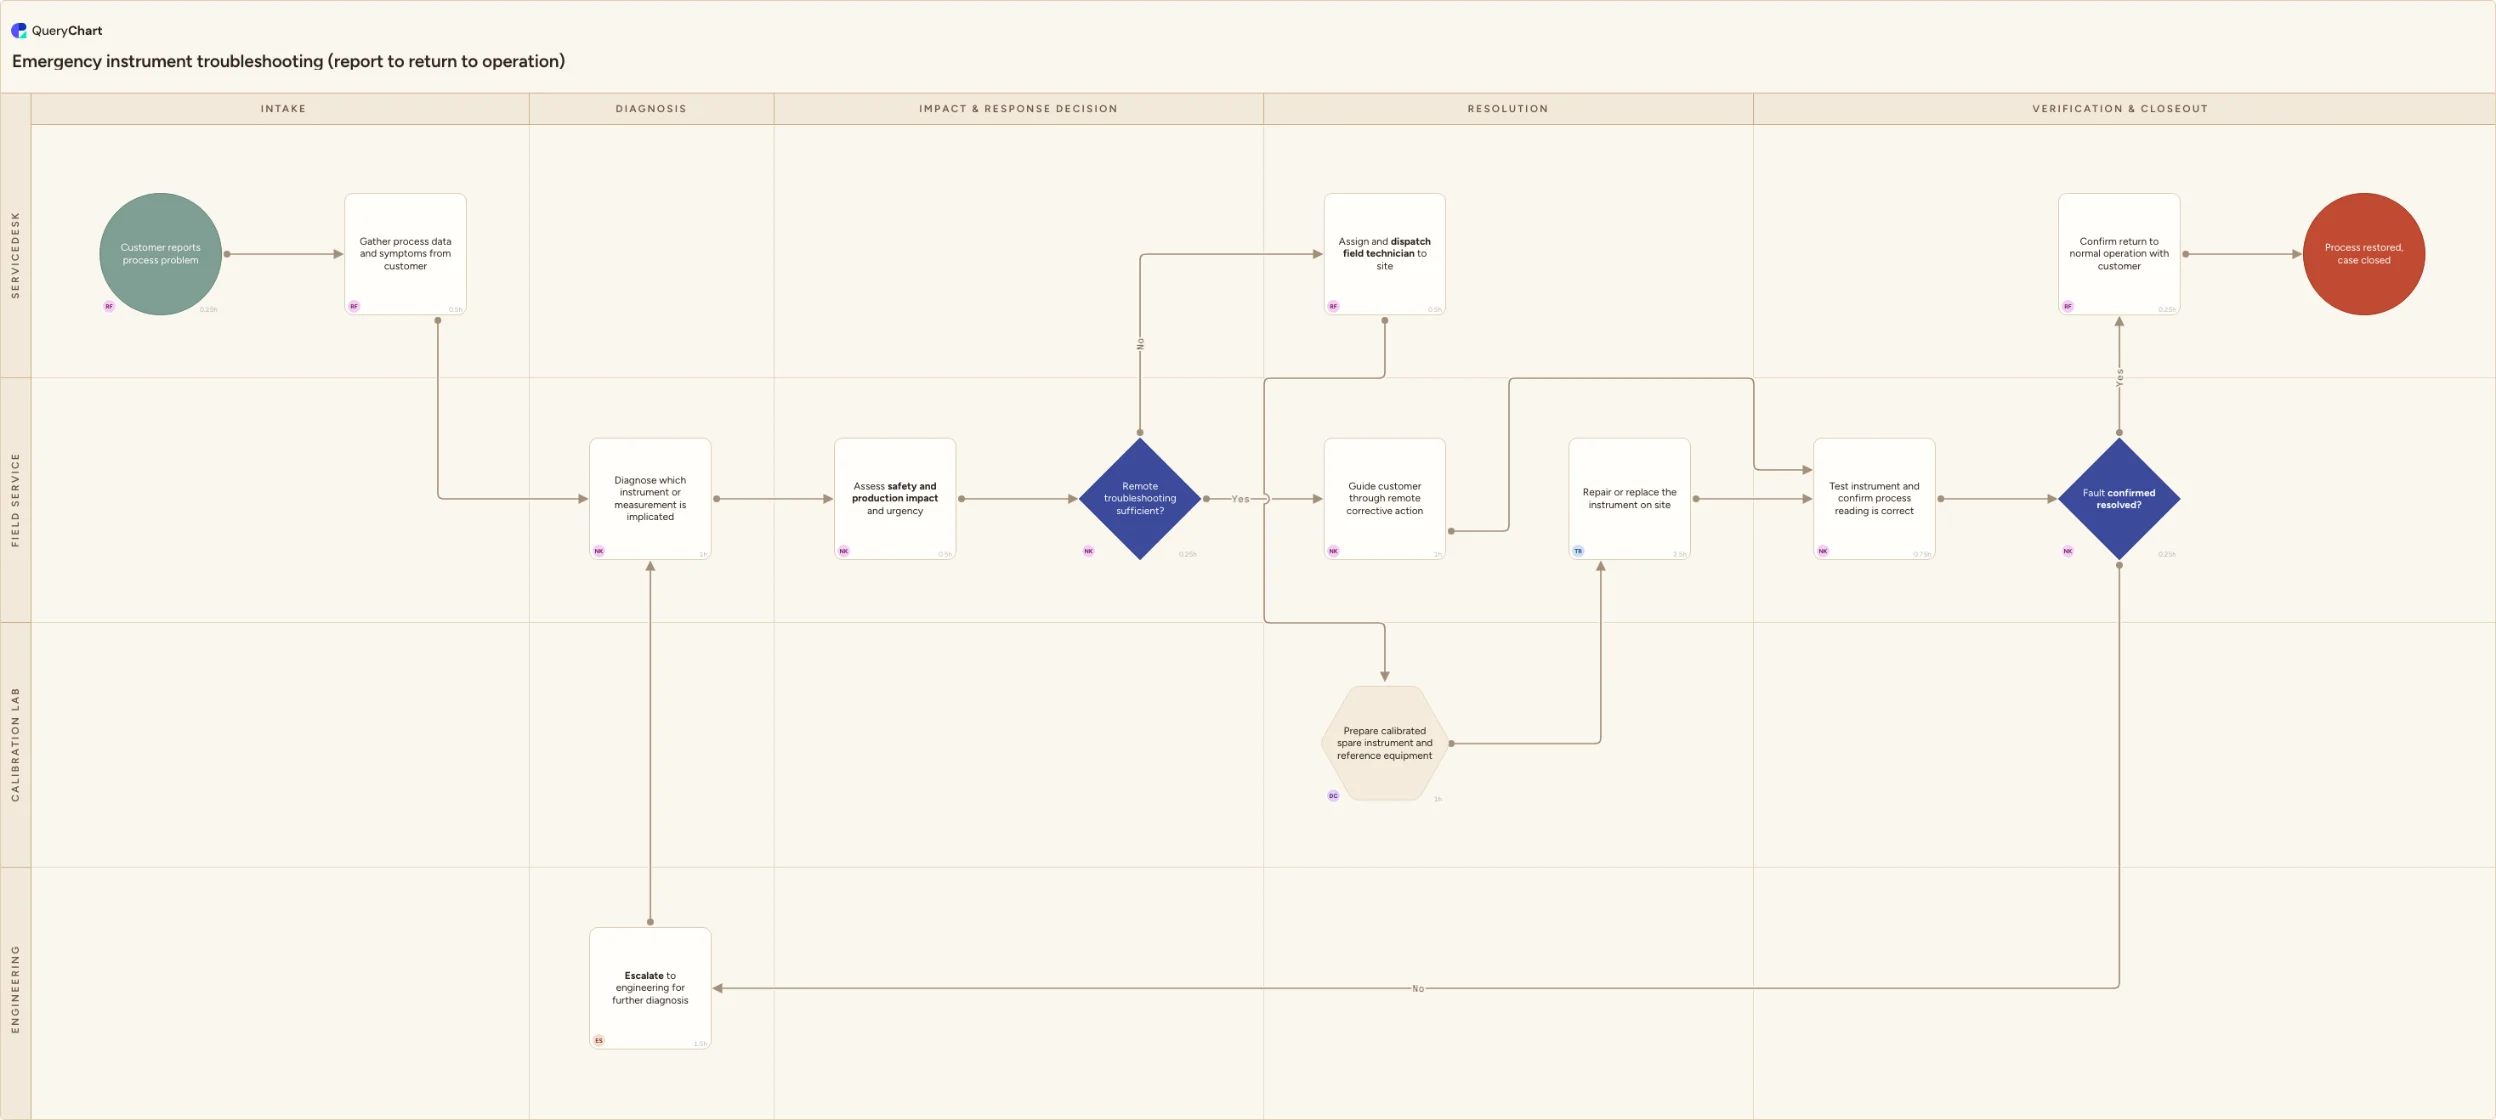
Emergency instrument troubleshooting SOP (instrumentation service provider)
An emergency instrument troubleshooting SOP: gathering process data on a fault that isn't yet named, diagnosing which instrument is implicated, weighing safety and production urgency, then choosing a remote fix or field dispatch.
What the emergency instrument troubleshooting SOP (instrumentation service provider) process is
A customer does not call Insatech's ServiceDesk to report that a transmitter has failed. They call to say the reactor temperature is drifting, a flow total does not match the mass balance, or an alarm will not clear, and at that moment nobody, not the operator on the phone and not the person taking the call, knows yet which loop is actually at fault. That gap is the reason this chart puts "Gather process data and symptoms from customer" and "Diagnose which instrument or measurement is implicated" before anything resembling a fix decision: a five-minute call that jumps straight to "send a technician" can dispatch someone to the wrong part of the plant, while a five-minute call that jumps straight to "try resetting it" can talk a customer through the wrong loop on a process that is still degraded. The diagnostic step exists because at intake the fault has a symptom, not yet a name.
"Assess safety and production impact and urgency" sits deliberately between diagnosis and the "Remote troubleshooting sufficient?" decision, not after it. A drifting level transmitter on a non-critical buffer tank and a failed pressure transmitter on a safety-instrumented loop produce the same kind of phone call, but they cannot get the same response, and Insatech cannot afford to find that out by first deciding how to fix it and only then asking whether the fix was urgent enough to justify a technician on the road. This is the urgent, unplanned sibling of the On-Site Service Request & Dispatch SOP: that SOP's ServiceDesk triage assumes the issue is already scoped and simply routes it remote-or-on-site on convenience and complexity, while this one starts from a process that is degraded right now, an instrument that has not yet been identified, and an impact call that has to be made before the remote-versus-dispatch decision, not folded into it.
The chart does not assume the first fix works. "Test instrument and confirm process reading is correct" feeds a second decision, "Fault confirmed resolved?", and a "No" routes to "Escalate to engineering for further diagnosis" rather than closing the case on a repair that has not actually been verified against the process. Every row also carries a named owner and an hours figure through the built-in People and Workload columns, so the workload BI panel can show, across a week of unplanned calls, how much of Nadia Kessler's time went to diagnosis and remote fixes versus how much of Thomas Reid's went to on-site repairs, on a process line where none of it was scheduled in advance.
What this flowchart covers
In this template
- Intake under diagnostic uncertainty: "Customer reports process problem" through "Gather process data and symptoms from customer" to "Diagnose which instrument or measurement is implicated", the step that turns a vague symptom into a named loop
- Impact assessment ahead of the decision: "Assess safety and production impact and urgency" runs before the "Remote troubleshooting sufficient?" decision, not after, so urgency is established while the response is still being chosen
- The remote-or-dispatch branch: a "Yes" leads to "Guide customer through remote corrective action", while a "No" leads to "Assign and dispatch field technician to site", "Prepare calibrated spare instrument and reference equipment" in the Calibration Lab lane, and "Repair or replace the instrument on site" in Field Service
- Verification before closeout: both paths converge on "Test instrument and confirm process reading is correct", which feeds the "Fault confirmed resolved?" decision rather than assuming the first fix held
- The re-diagnosis loop: a "No" on "Fault confirmed resolved?" routes to "Escalate to engineering for further diagnosis" and back into the diagnosis step, instead of leaving an unresolved case marked closed
- Named owners and hours on every row via the People and Workload columns, so the workload BI panel can separate Nadia Kessler's remote-diagnosis hours from Thomas Reid's on-site repair hours across a week of unplanned emergency calls
When to use this template
- You're standardising how Insatech's ServiceDesk and Field Service handle an urgent, unscoped process complaint, where the caller cannot yet tell you which instrument is wrong, and want the diagnosis-before-decision order fixed on one chart instead of left to whoever picks up the phone
- You need a clear line between this SOP and the On-Site Service Request & Dispatch SOP: this one is for a process degraded right now with the instrument still unidentified, the other for a request that is already scoped
- A technician was dispatched for something that turned out to be resolvable by phone, or a customer was talked through a fix on a loop that actually needed a safety-critical instrument swap, and you want the impact-before-decision gate to catch that earlier next time
- You're onboarding a new ServiceDesk coordinator or field technician and need a reference for exactly what gets asked and assessed before a remote-or-dispatch call is made
- A first repair did not hold and you want a documented escalation path into further diagnosis instead of the case quietly being reopened as if it were new
How it works
Replace the lanes with your actual response roles
This chart uses ServiceDesk, Field Service, Calibration Lab and Engineering. If your ServiceDesk and dispatch functions are split, or a separate specialist team owns escalated diagnosis, give that role its own lane rather than folding it into Field Service, since the handoff is usually where a symptom gets assumed diagnosed by someone who assumed someone else had already narrowed it down.
Write real urgency criteria into the impact assessment
"Assess safety and production impact and urgency" needs a stated basis, such as whether the implicated loop is safety-instrumented, tied to a permit limit, or driving a production stoppage, not just a gut call. Put the actual criteria into the row's comment field so the person making the remote-or-dispatch decision isn't relying on memory of what counts as urgent.
Set a real threshold on the remote-vs-dispatch decision
"Remote troubleshooting sufficient?" is only a safe branch if there's an agreed line for when phone guidance stops being appropriate, for example any safety-instrumented loop or any repeat call on the same fault. State that threshold explicitly rather than leaving it to whoever is on the call that day.
Set People and Workload on every row before you rely on the BI panel
The workload panel can only total hours for rows that carry them. Fill in People and Workload for each step as you adapt the chart, using realistic effort hours rather than elapsed time, so an unplanned emergency week actually shows up as a busy week for the right person.
Decide what closes the re-diagnosis loop
"Fault confirmed resolved?" only works if there's a stated test, such as a stabilised reading over a defined period, that counts as confirmation. Otherwise a technician under time pressure can mark a fault resolved on the first plausible fix instead of a verified one, and the loop back through "Escalate to engineering for further diagnosis" never fires when it should.
Frequently asked questions
What triggers the start of the emergency troubleshooting process?
The process starts at "Customer reports process problem": a customer calls describing a process that is behaving wrong, not a named instrument fault. "Gather process data and symptoms from customer" and "Diagnose which instrument or measurement is implicated" exist precisely because, at this point, which loop is actually at fault is not yet established.
How is this different from the On-Site Service Request & Dispatch SOP?
On-Site Service Request & Dispatch assumes the issue is already scoped and simply triages an already-understood request between remote support and a site visit. This SOP starts earlier and under more pressure: a process degraded right now, an instrument that hasn't been identified yet, and a safety/production impact assessment that has to happen before the remote-or-dispatch call, not folded into it.
Why does impact assessment come before the remote-vs-dispatch decision instead of during it?
"Assess safety and production impact and urgency" is a separate row that runs before "Remote troubleshooting sufficient?" so urgency is established on its own basis, such as whether a safety-instrumented loop is implicated, rather than getting folded into the convenience of whichever response happens to be easier to arrange that day.
What happens if the fix, remote or on-site, doesn't actually resolve the fault?
Both paths converge on "Test instrument and confirm process reading is correct", which feeds the "Fault confirmed resolved?" decision. A "No" routes to "Escalate to engineering for further diagnosis" and back into diagnosis, so an unresolved case is re-diagnosed with specialist input instead of being closed on an unverified fix.
Who decides whether a spare instrument is swapped in rather than repaired?
That decision sits inside "Prepare calibrated spare instrument and reference equipment" in the Calibration Lab lane: for a safety-instrumented or production-critical loop, a straight swap from calibrated lab stock is usually faster and more certain than a field repair attempt, which is why the row exists as its own step rather than being folded into "Repair or replace the instrument on site".