How to create an incident management process
How to design an incident management process where severity sizes everything downstream: classify before diagnosing, draw re-classification as a route, and hand the cause to a separate record.
An incident management process restores a service on a path sized to the severity of the incident, then hands the unanswered question of cause to a separate problem record once the service is back.
The short version
- Priority is computed from the intake fields, not from how bad the incident feels.
- One path for every incident is too heavy for the small ones and too quiet for the serious ones.
- Raising or lowering severity mid-incident needs its own drawn route, which most charts omit.
- Restoring the service and explaining it are two processes with a handoff between them.
- Closure needs the reporter's confirmation, not the engineer's confidence.
Severity is not a field, it is the process
Incident management restores a service and then accounts for what happened. The version most organisations draw first is a single path (log, diagnose, fix, close) and it fails in both directions at once. It is too ceremonial for the printer nobody can reach, so people stop raising tickets and ring a colleague instead, and it is far too quiet for the outage that should have woken three people up.
Priority is set from impact and urgency before anyone knows what is broken, and everything after it is sized by that one call: who gets rung, how often stakeholders hear from you, which clock the fix is measured against. Classification is therefore the load-bearing step, and it is made on partial information, so it will sometimes be wrong, which means re-classification belongs on the map as a drawn route rather than as a quiet edit to a field.
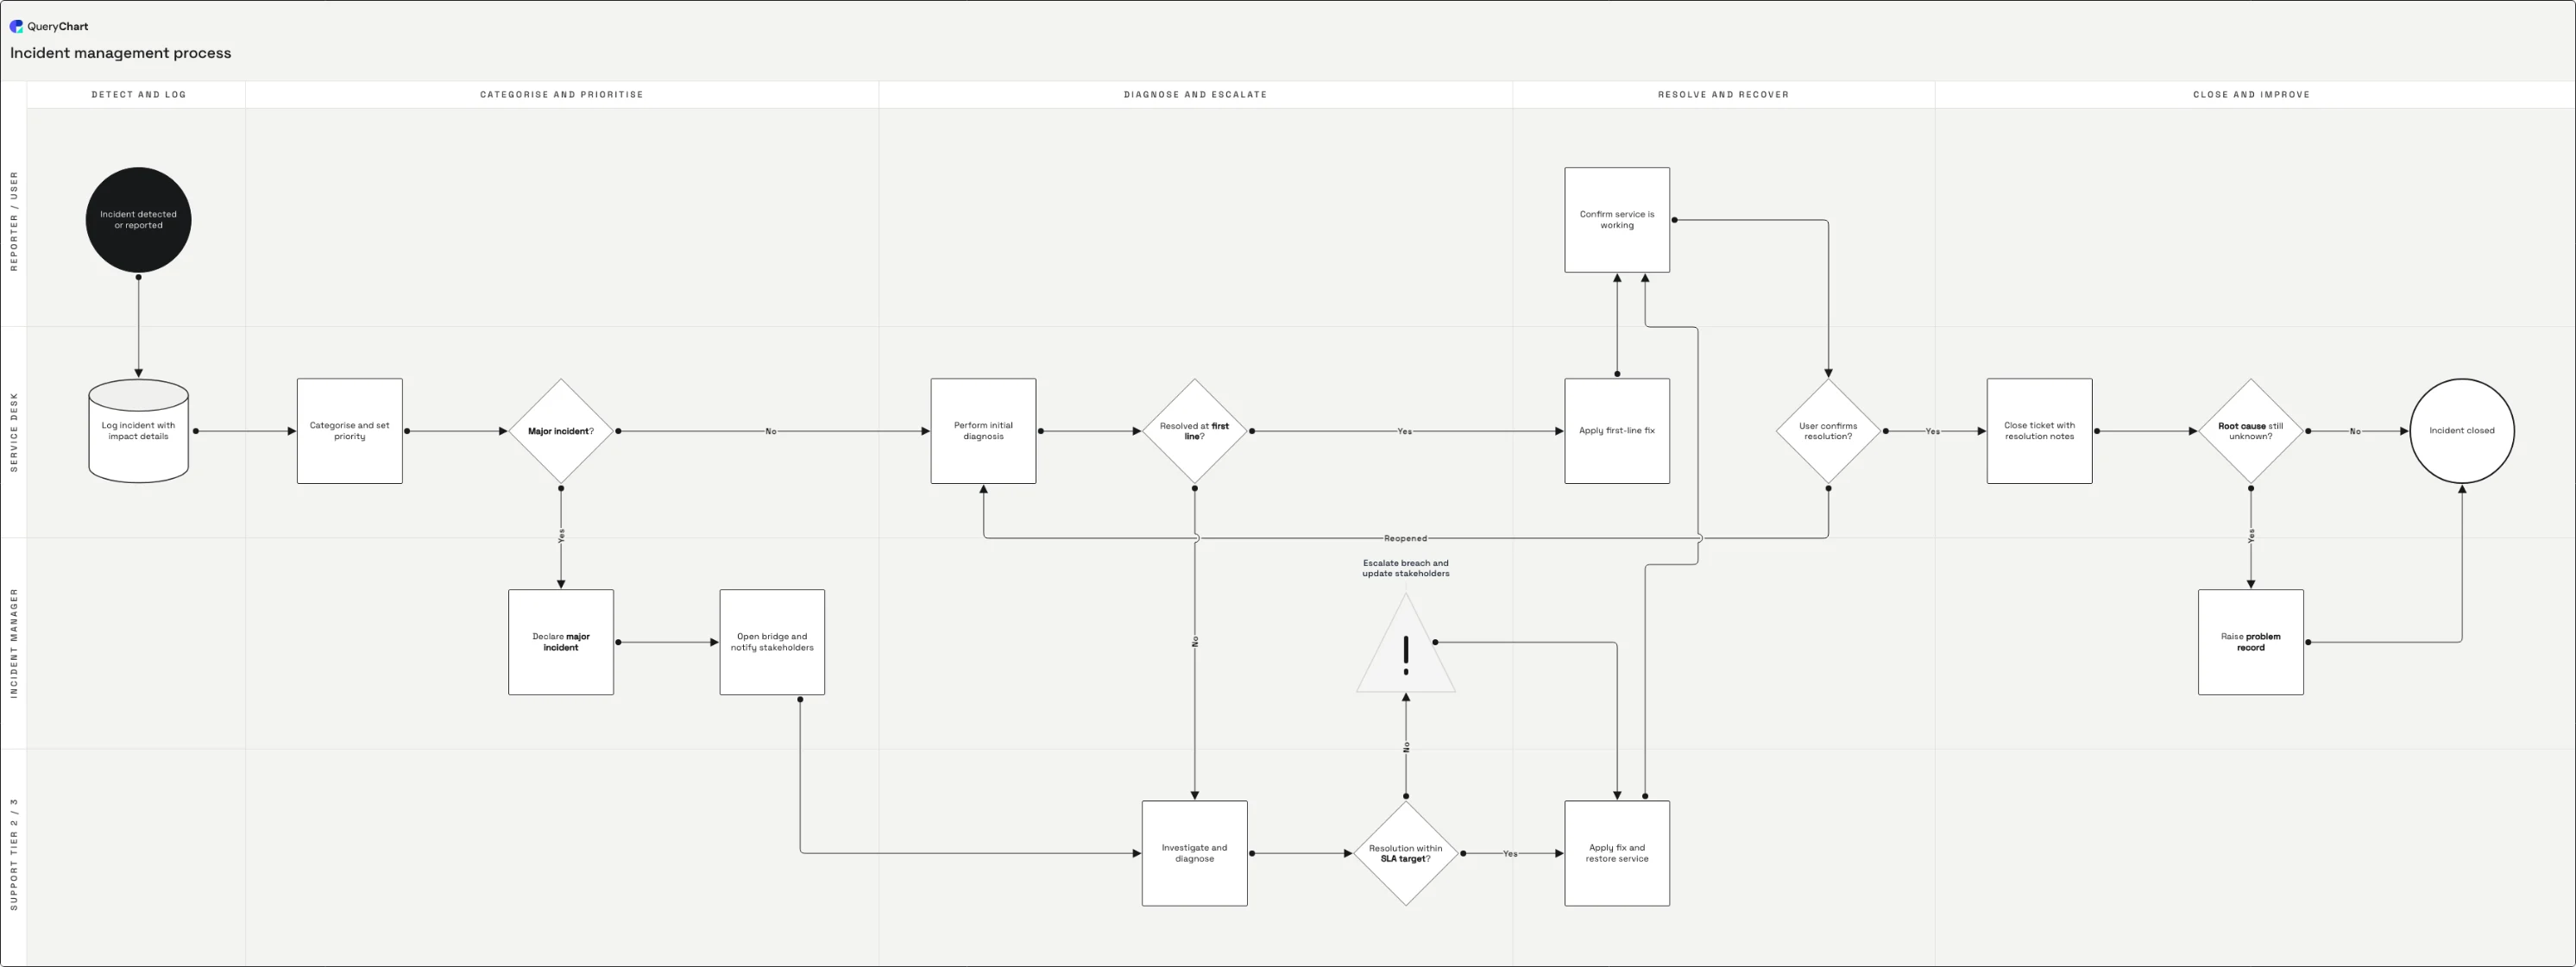
The example runs an incident across five phases and four lanes, and the row worth staring at is "Investigate and diagnose": a declared major incident and a ticket first line could not fix both land in the same box. Severity decides who is called and which clock runs, not who eventually does the diagnosing: that is the honest limit of the chart's proportionality. Note too that "Root cause still unknown?" is asked in one place for every severity, which is why a P1 and a P4 leave the same evidence behind.
One severity call, everything after it
Watch how much "Major incident?" settles before anyone diagnoses anything: a bridge, a stakeholder notice and a change of owning lane.
A thin ticket is a wrong priority
Intake is two rows: "Incident detected or reported" and "Log incident with impact details". Everything the priority is computed from is captured in the second (affected service, how many people, when it started, the symptoms), so a thin ticket does not delay the classification, it corrupts it.
Severity sizes what follows
The "Yes" exit of "Major incident?" is not a louder version of the same path: "Declare major incident" and "Open bridge and notify stakeholders" both happen before anyone diagnoses anything, and ownership moves from Service Desk to the Incident Manager lane. The "No" arm arrives next.
Two routes to a restored service
"Resolved at first line?" keeps the small ones short: its "Yes" exit goes to "Apply first-line fix". The rest join the Support Tier 2 / 3 lane, where "Resolution within SLA target?" is asked after diagnosis, so "Escalate breach and update stakeholders" reports a breach it is too late to prevent.
The reopen skips classification
The "Reopened" exit from "User confirms resolution?" re-enters at "Perform initial diagnosis", which sits below the severity call, so a reopened incident is diagnosed again but never re-classified, whatever the second failure has cost by now. "Raise problem record" is where the cause leaves.
How it works
Write the priority matrix before the chart
Priority is impact against urgency, and both need stated levels: how many users, which service tier, whether money or safety is involved, how fast the damage grows, whether a workaround holds. Agree those first, because a matrix invented while mapping describes the last incident rather than the next one.
Decide what a major incident actually changes
List what the declaration buys: a named owner, a bridge, updates on a fixed clock, permission to bypass normal change approval. If nothing changes except the label, the branch is decoration. The example spends two whole steps on it, which is the honest amount of work involved.
Type intake and classification as rows
Each row in QueryChart is a box. Put the trigger in the Box text column, then the logging step, then the categorisation step, and point each row at the next in the Line to column. Three rows in, the map has made its argument: the priority on row 3 is computed from what row 2 captured, which makes row 2 a design decision and not a form.
Fork the severity call and label both exits
Change the classification row's Shape column to Decision, list both destinations in Line to, then give each number its answer in Line text. The chart forks once, at "Major incident?", though the matrix has four or five levels, and those two labels do more work than any other pair here, because they are the only place the route changes.
Point the reopen path at a lower row number
A fix the reporter rejects goes back to diagnosis: the "Reopened" exit from row 15 points at row 7. A severity called wrong needs the same treatment and the example does not draw it: add a branch from the diagnosis rows back to "Categorise and set priority". Each is a lower number in the Line to column.
Calibrate the matrix, then name who declares
Put the matrix where whoever logs the ticket can read it, then test it: give two people on opposite shifts the same three descriptions and compare what they set. Disagreement means a missing level, not a careless colleague. Then name the person on each shift who may answer Yes at "Major incident?" before the Incident Manager is awake.
Mistakes to avoid
Classifying after the diagnosis
By then the escalation that mattered has not happened, and the priority field records only how bad it turned out. Impact and urgency are answerable before the cause is, which is why the classification row sits at three.
The severity it was born with
Impact grows; the priority does not. Set once in the Service Desk lane, it fixes the call list and the clock, and the chart's one backward route re-enters below it. Draw re-classification as a route and name who may take it.
Reopening by raising a new ticket
The original closes inside target, a second ticket starts a fresh clock, and the reporting shows two quick fixes instead of one failed one. Draw the reopen as a return to diagnosis on the same record.
Problem records with no owner
"Raise problem record" is a row, not an outcome. A record with no owner, no date and no link back to the incidents that produced it is closure paperwork, and it gets closed unread at the next tidy-up. Name both when you raise it.
Create your own incident process
Open the incident example as your own chart, put your severity thresholds on the classification row and your on-call roles in the lanes.
Related guides
Frequently asked questions
What is the difference between an incident and a problem?
An incident is an interruption to a service; a problem is the underlying cause of one or more incidents. They are kept as separate processes because they run on different clocks: incident management is measured on time to restore, problem management on whether the cause has actually been removed, which can take weeks. Merging them means the cause work inherits the incident's urgency and is abandoned the moment the service comes back.
How do you decide incident priority?
From impact and urgency on a published matrix, not from who is asking. Impact is how much of the organisation is affected: users, sites, service tier, whether money or safety is involved. Urgency is how fast the damage grows and whether a workaround holds. The matrix turns that pair into a priority, and it earns its place only if the figures behind the call are recorded alongside it: a priority nobody can reconstruct cannot be challenged when it turns out to be wrong.
When should an incident be declared a major incident?
When it crosses a threshold agreed in advance: a tier-one service down, a stated number of people unable to work, regulatory or safety exposure, a suspected breach. The declaration only earns its place if it changes behaviour: a named incident manager, a bridge, updates on a fixed cadence. Declaring late is the common failure, and the cost of declaring and then standing down is far lower than the cost of an hour of quiet.
Should a reopened incident be a new ticket?
No: reopen the original, because the two records answer different questions. A new ticket resets the resolution clock and reports one failed fix as two successful ones, which is precisely the distortion that hides an unstable service. Reopening on the same record keeps the history in one place and makes the reopen rate measurable, and reopen rate is the most honest quality signal an incident process produces.